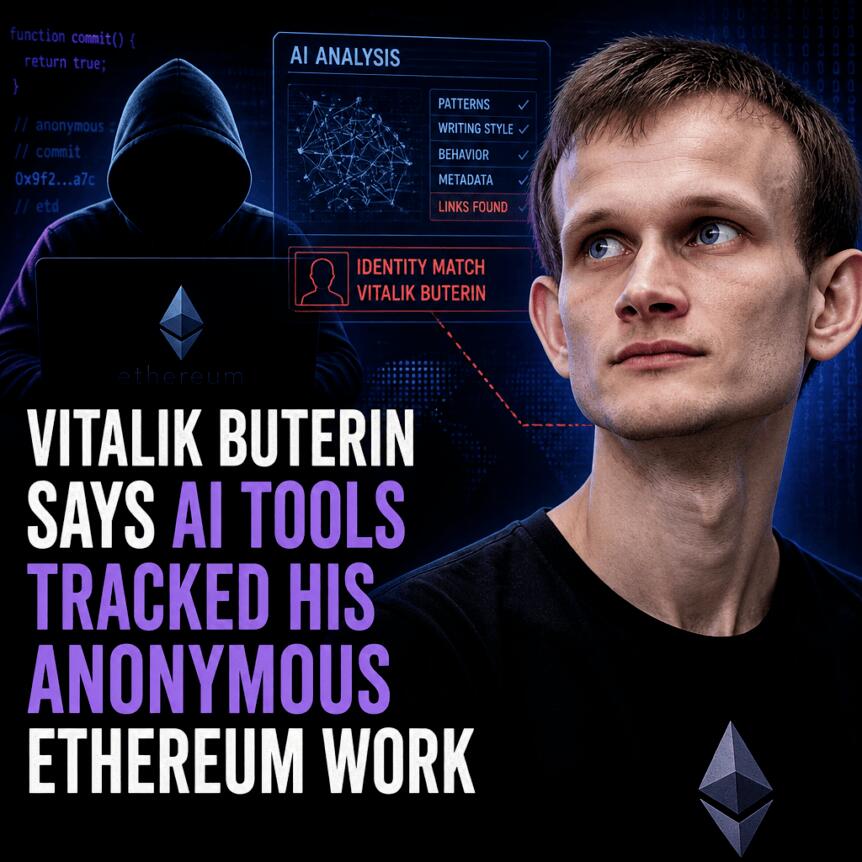
Ethereum co-founder Vitalik Buterin has confirmed that AI-assisted analysis by Co-Invest CEO Franklyn Wang correctly pinpointed his anonymous authorship of a rewrite of EIP-7503. The result follows Buterin’s own public challenge earlier this month, where he asked whether today’s AI tools could reliably undo online anonymity.
Wang says the identification succeeded not because of the document’s surface-level wording, but because of the underlying reasoning patterns used to explain mathematical and technical ideas—suggesting that even deliberate obfuscation, such as translating content from another language, may not fully protect anonymous technical contributions.
Key takeaways
- Buterin confirmed Wang’s system identified him as the author behind an anonymous EIP-7503 rewrite.
- Wang’s explanation emphasizes reasoning and the structure of explanations, not just writing style.
- The test was prompted by Buterin’s skepticism about whether AI could realistically deanonymize authors.
- Prior research Wang referenced claims large language models can perform deanonymization at scale from unstructured text.
A high-profile test of deanonymization
Buterin’s June 22 post was unusual for the crypto community: rather than defending his privacy, he deliberately offered a puzzle about his own past anonymity. He said he had published a document—described as “medium importance” to Ethereum—under a different name and challenged the public to find it.
The premise was rooted in a broader debate inside tech: whether large language models can infer identity from writing. While anonymity remains common in open-source and technical ecosystems, some analysts argue that as AI models improve at extracting patterns from text, pseudonymous participation could become harder to sustain.
That question was sharpened by a February paper from researchers at ETH Zurich and Anthropic. The study argued that large language models can make online deanonymization practical at scale by identifying identity-related information in unstructured text, generating candidate matches, and then reasoning over the most likely authors. It also claimed to outperform traditional deanonymization techniques.
How Wang’s analysis reportedly worked
Two weeks after Buterin’s challenge, Wang posted on X that his submission correctly identified the anonymous EIP-7503 rewrite. He said the document’s author had hidden the work by writing it in Chinese and machine-translating it. Yet, according to Wang, the system found a “tell” that did not come from the author’s choice of words.
“The doc was an anonymous EIP-7503 rewrite he’d hidden by writing it in Chinese and machine-translating it,” Wang wrote in a Monday X post after Buterin confirmed the result. “The tell wasn’t his words, it was his reasoning.”
Wang further stated that Co-Invest ranked Buterin as the most likely author of the anonymous December 2024 rewrite of EIP-7503, with roughly 20% confidence—about 10 times higher than the next candidate—based on an analysis of 27 documents.
Buterin’s obfuscation and why it didn’t hold
After Wang’s identification, Buterin revealed additional details about how he attempted to disguise authorship. He said he had written the anonymous rewrite in Chinese, translated it into English using Qwen 2.5, and then manually corrected the translation with the intent to make his prose harder to attribute.
Buterin’s follow-up explanation suggested that the approach targeted the wrong surface layer. He wrote that “stylistic hints” the AI picked up on were tied to intellectual habits—specifically the style of mathematical and algorithm explanations—rather than the prose itself. In other words, while translating and editing prose may change diction and phrasing, it may not eliminate deeper patterns in how a writer structures explanations and arrives at technical descriptions.
He added that those reasoning-level signals “bypass[ed]” his obfuscation strategy, which he characterized as covering prose only.
Limits and lessons from earlier attempts
The deanonymization debate is not new, but this case adds a real-world datapoint because it ties back to a question Buterin publicly raised. The episode also intersects with earlier work within the crypto AI space.
Lighter CEO Vladimir Novakovski said on Monday that he worked with Wang in 2023 on a project using GPT-4 to try to identify Bitcoin creator Satoshi Nakamoto by matching writing style in cryptography research. Novakovski said that effort failed to produce a high-confidence result.
According to Novakovski, Wang later applied a similar approach to Buterin’s anonymity challenge—yet in this instance the identification reached confirmation from the person targeted by the test.
That distinction matters: it implies that while AI-based author inference can be unreliable in some contexts, it may become more accurate when the text and task conditions allow models to capture consistent explanation patterns. It also highlights that “deanonymization” isn’t a single technique; performance may vary depending on language, document type, candidate set size, and how much of the author’s reasoning becomes visible in the writing.
Why this matters for crypto builders and contributors
In open-source and standards work—where proposals, research notes, and technical explanations often circulate publicly—pseudonymous authorship can protect individuals from harassment, reduce reputational pressure, and encourage candid experimentation. But if AI systems can attribute authorship by tracing reasoning patterns, then anonymity could become more fragile than many contributors assume.
At the same time, the episode doesn’t prove that every anonymous contribution is doomed. The earlier Nakamoto-attribution attempt reportedly failed to achieve high confidence, and in practice, the effectiveness of deanonymization likely depends on how easily models can extract stable, identity-linked signals from the text.
For investors, traders, and ecosystem participants, the broader takeaway is that AI capabilities are increasingly reaching beyond generating content into analyzing provenance—especially in technical domains where reasoning needs to be explicit. That shift may affect how communities think about privacy, attribution, and risk in public documentation.
Readers should watch whether similar challenges—especially those involving different document formats, languages, or candidate sets—continue to confirm or contradict Wang’s approach, and whether communities adjust norms around anonymity in Ethereum standards and other technical workflows.